不是对局,而是帮助
与围棋和五子棋不同,数独没有对手。如果 AI 自己把题全部解完,人就无事可做了。所以在网页版数独(stoku.mariago.kr)中,由人亲自解题,只有在卡住时才向 AI 询问一步。
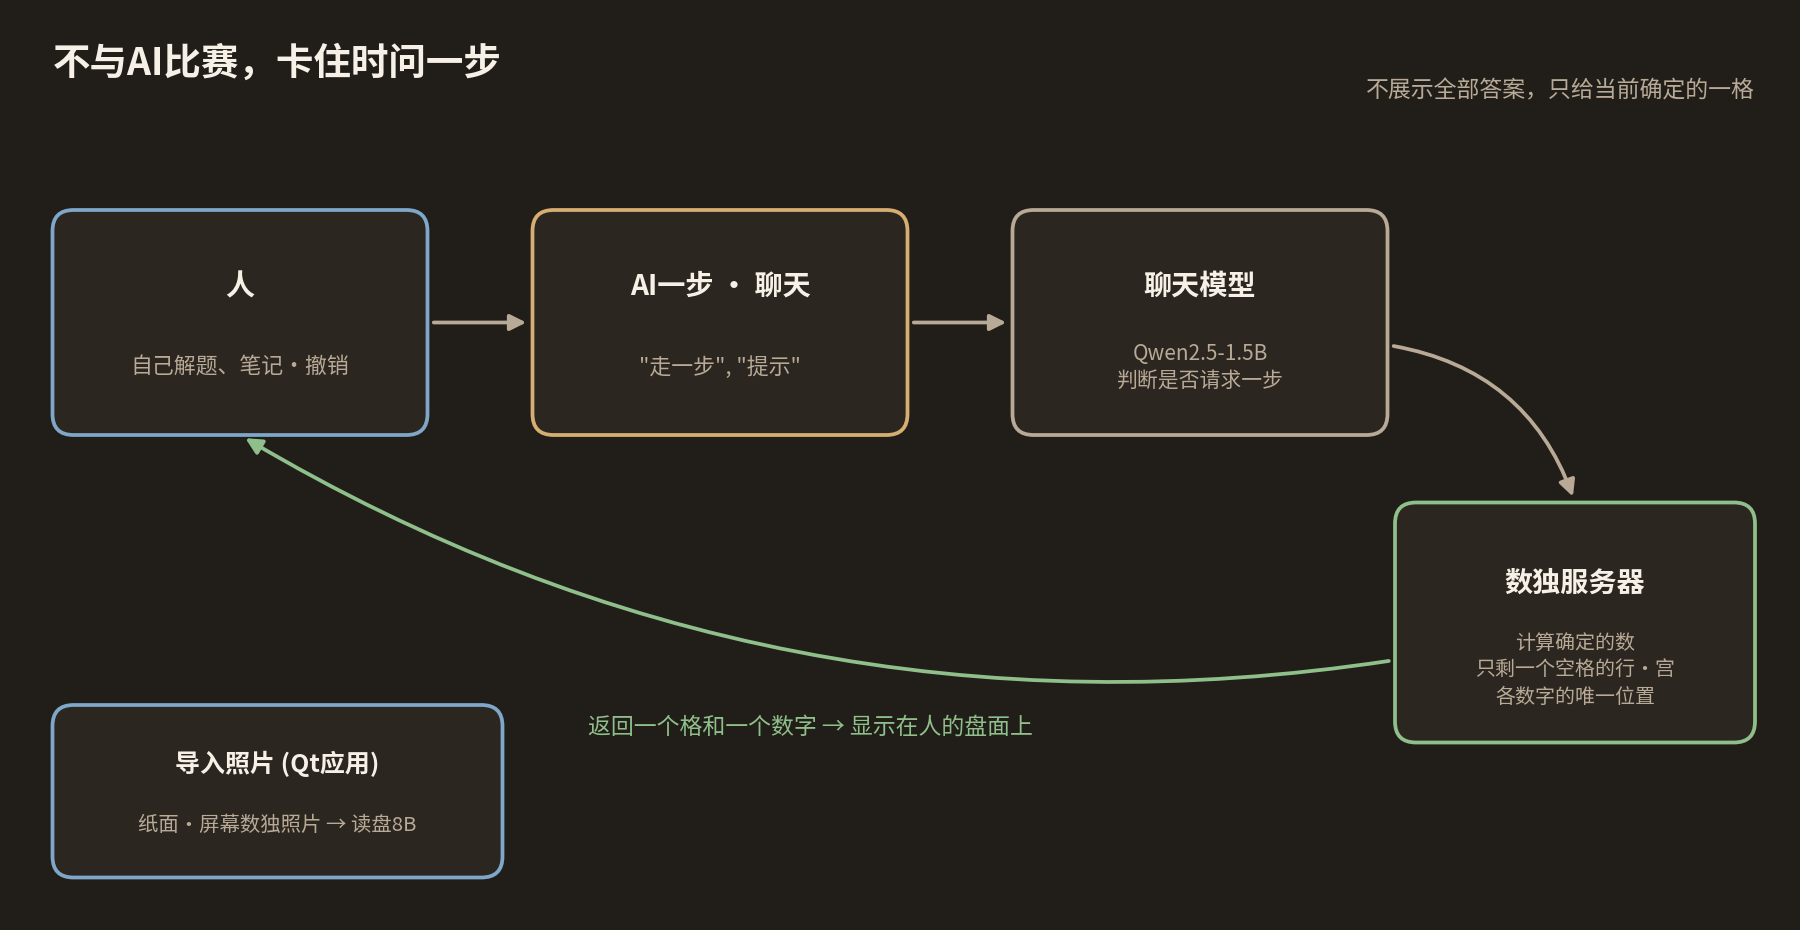
询问一步的途径
- 通过画面上的“AI 一步”按钮或聊天来询问,比如“走一步”“提示”这样的话。
- 聊天服务器用 Qwen2.5-1.5B-Instruct 和正则表达式判断是不是请求一步。
- 如果是请求一步,就把当前盘面发给数独服务器,收到一个格子和一个数字后放到人的盘面上。
现在的网页服务器不加载 VLM,只用代码挑选确定的一步。它先看只剩一个空格的宫、行、列,如果没有,再按数字寻找只有一个位置可填的格子。相当于第 4 篇中 VLM 和代码分担的工作全部由代码来完成。画面上的模型列表显示的是 lora_move,但实际的一步由这个策略决定。目前还不会显示为什么是那个格子。
从照片导入
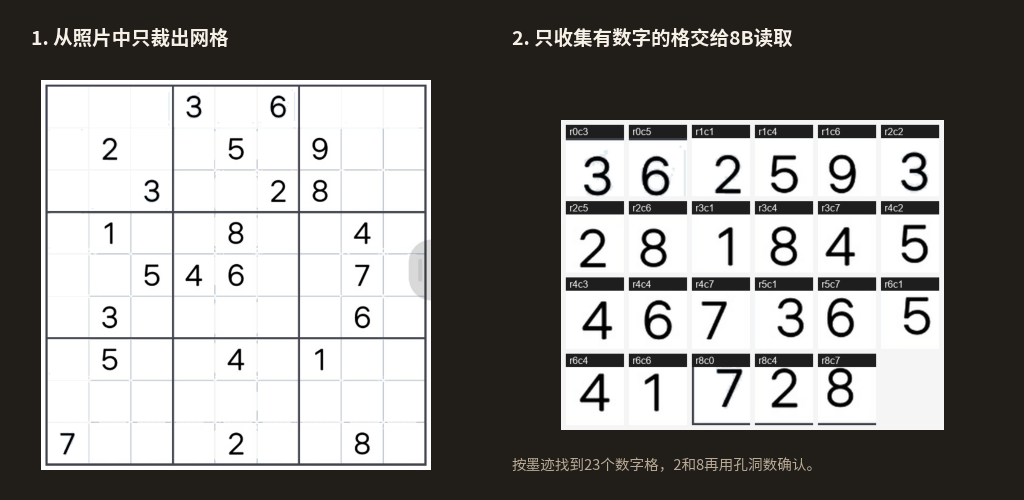
Qt 应用有一个功能,可以把纸上或屏幕上的数独以照片形式导入。它会裁出网格,只收集有数字的格子,交给第 3 篇中读取盘面的 8B LoRA 来识别。
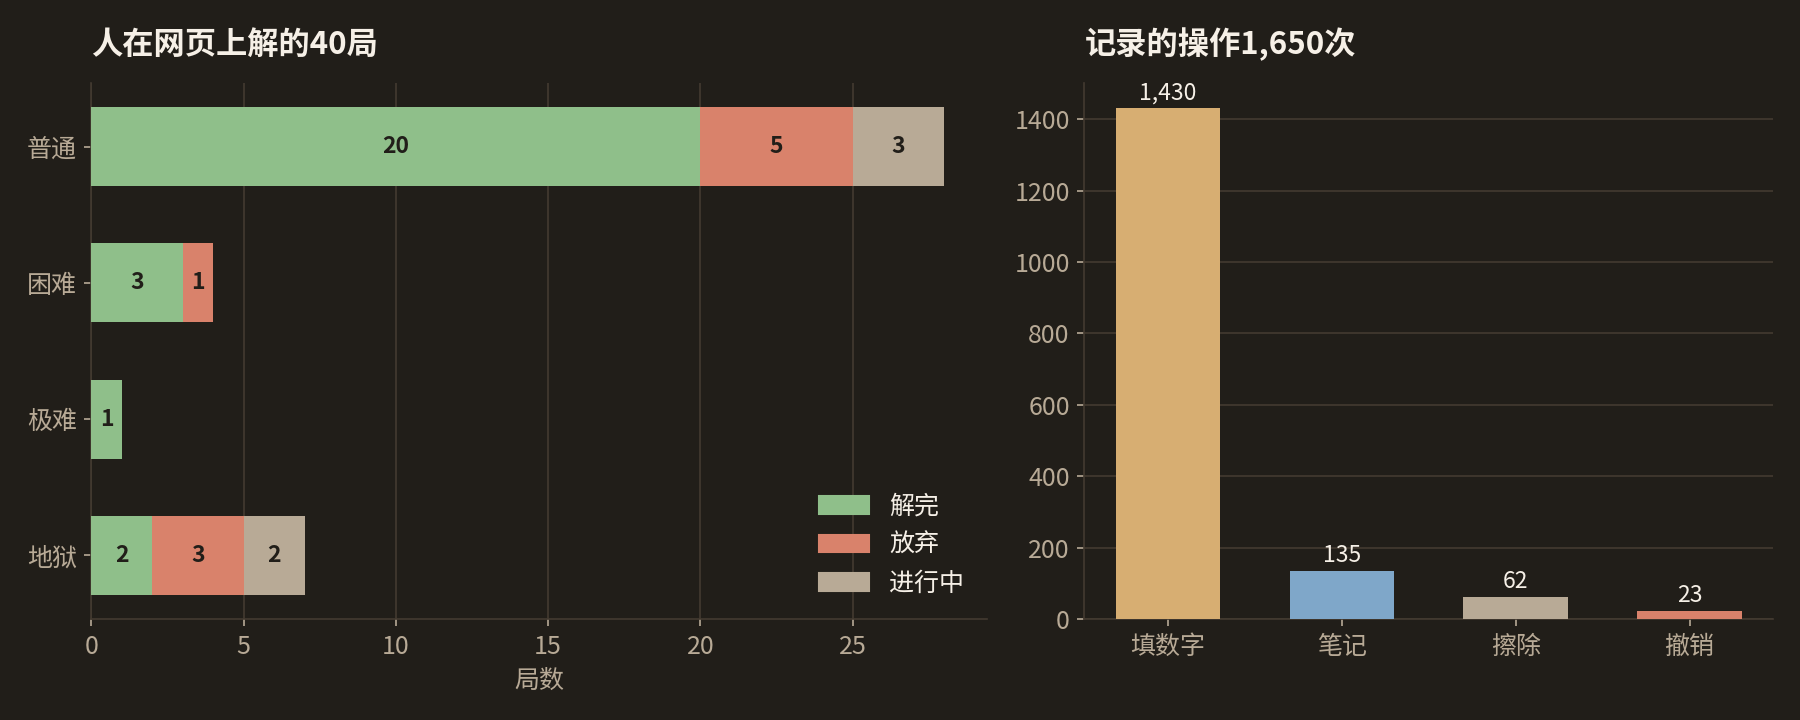
网页上的解题记录
在三周多的时间里,网页上共开了 40 局。其中 26 局解到了最后,平均用时约 12 分钟。9 局中途放弃,5 局仍处于进行中。解完的局中,普通 20 局、困难 3 局、地狱 2 局、极难 1 局。
记录下来的操作有:填数字 1,430 次、笔记 135 次、擦除 62 次、撤销 23 次。
这一阶段的实际代码
这是网页服务器挑选确定一步的顺序。
vlm_digit_strategy.py
def pick_code_certain_move(
    board: list[list[int]],
) -> tuple[int, int, int, str] | None:
    """우선순위: last-empty → digit 유일 → human solver → 탐색 강제수."""
    lasts = last_empty_unit_moves(board)
    if lasts:
        return lasts[0]

    for digit in range(1, 10):
        illegal = set(illegal_cells_for_digit(board, digit))
        moves = absolute_placements(board, illegal, digit)
        if moves:
            r, c, v, reason = moves[0]
            return r, c, v, f"code_digit{digit}_{reason}"

    from sudoku_human_solver import find_human_move

    hm = find_human_move(board)
    if hm is not None:
        return hm.row, hm.col, hm.value, f"human_{hm.kind.value}"

    # 극한: 국소 후보는 여러 개인데, 하나만 해가 남는 칸 (예: 2행 끝 7)
    return pick_search_forced_move(board)
这是聊天服务器接收消息、如果是请求一步就转交给数独服务器的部分。
chat_bridge_server.py
MOVE_RE = re.compile(
    r"(한\s*수|다음\s*수|힌트|추천|어디|둬|놓|채워|풀어|solve|hint|move|next)",
    re.I,
)

# ...

def handle_chat(body: dict[str, Any]) -> dict[str, Any]:
    message = str(body.get("message") or "").strip()
    if not message:
        return {"error": "empty message"}

    model_id = str(body.get("modelId") or "lora_move")
    meta = TRAINED_MODELS.get(model_id, TRAINED_MODELS["lora_move"])
    board = body.get("board")
    puzzle = body.get("puzzle")
    difficulty = body.get("difficulty") or "medium"

    if not isinstance(board, list) or len(board) != 9:
        return {"error": "board required"}

    blanks = _empty_count(board)
    intent = classify_intent(message)

    llm_text = chat_llm_reply(
        message,
        {
            "model_label": meta["label"],
            "blanks": blanks,
            "difficulty": difficulty,
        },
    )

    if llm_text:
        if "CMD:MOVE" in llm_text.upper() or intent == "move":
            intent = "move"
        reply_base = re.sub(r"CMD:\w+", "", llm_text, flags=re.I).strip()
    else:
        reply_base = ""

    if intent == "move" or (intent == "unknown" and MOVE_RE.search(message)):
        result = call_trained_vlm(board, puzzle if isinstance(puzzle, list) else None, model_id)
        if not result.get("ok"):
            return {
                "reply": (
                    f"{meta['label']} 호출 실패: {result.get('error')}\n"
                    f"(채팅 AI → 학습 모델 명령 전달)"
                ),
                "action": None,
                "vlm": result,
            }
        r, c, v = result["row"], result["col"], result["value"]
        spoken = reply_base or (
            f"{meta['label']}에 「한 수」 명령을 전달했습니다."
        )
        return {
            "reply": f"{spoken}\n→ ({r},{c}) = {v}",
            "action": {"type": "place", "row": r, "col": c, "value": v},
            "vlm": result,
        }
下一篇是“6. 完整源代码与使用的模型”。
COMMENTS · CHAPTER 05
帮助人的 AI 评论 0
还没有评论。阅读时有疑问或想补充的内容,欢迎留言。
发表评论前,请用 Google 开始并登记昵称和邮箱。
用 Google 开始