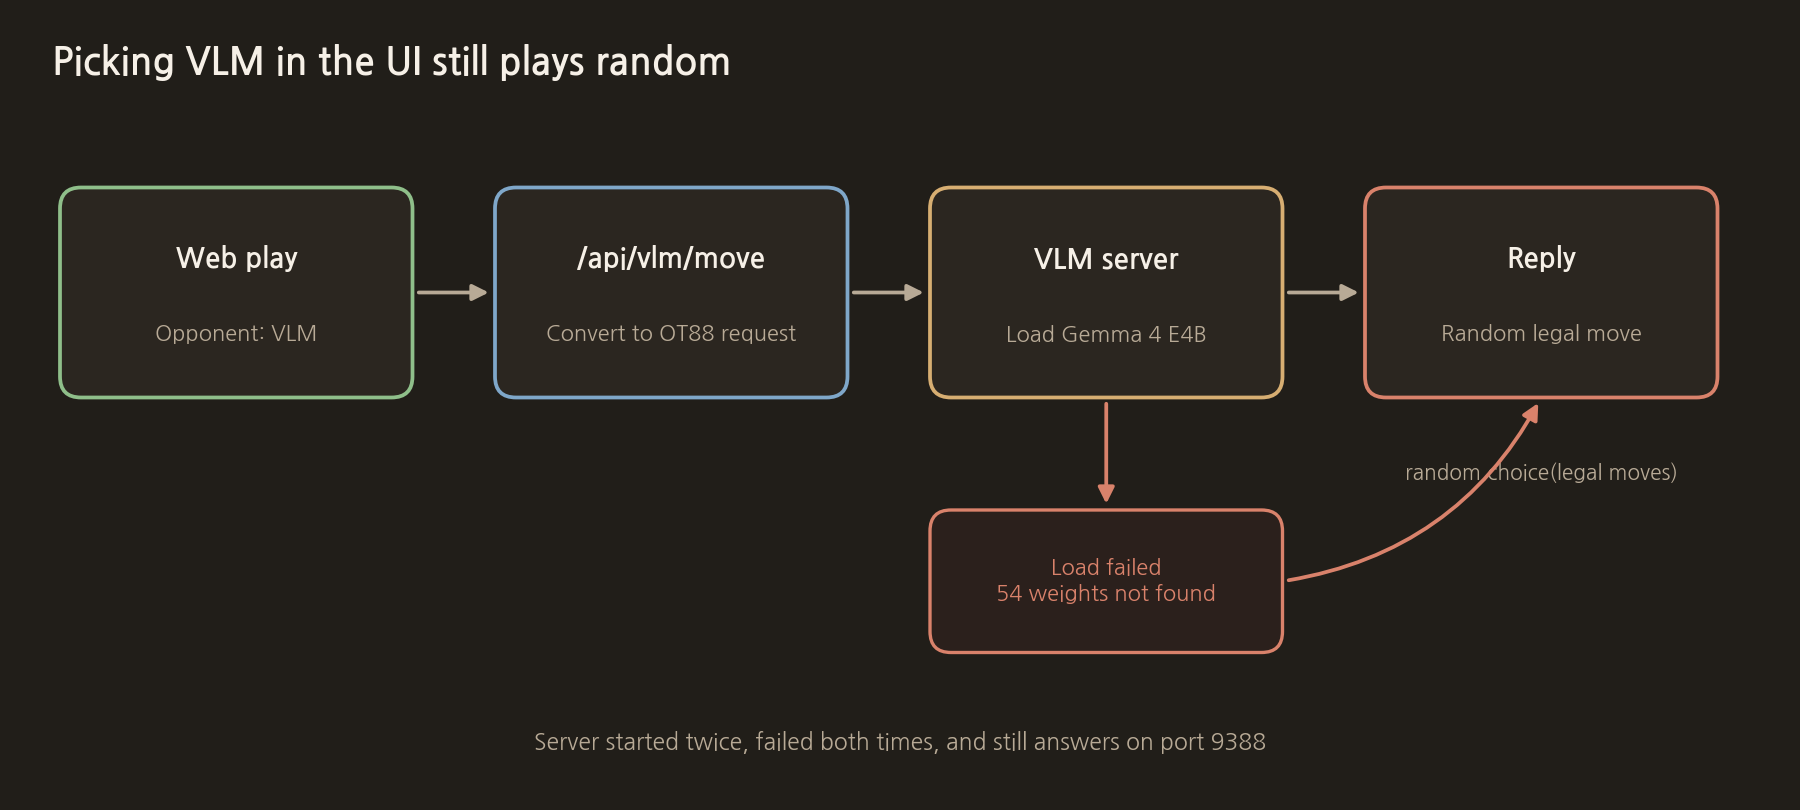
The VLM server
The VLM server loads Gemma 4 E4B (mlx 4bit) with mlx-vlm and has it pick a move from a board image and text. It receives requests from the Qt app and the web via the OT88 protocol, built on the same frame as GO19 for Go. The prompt includes the list of legal moves.
Load failure
The server log shows two startups, and both failed with the same error.
ValueError: Missing 54 parameters
The missing weights are self_attn k_proj, v_proj and k_norm in layers 24–41 of the language model. The installed mlx-vlm is 0.5.0. The model files and the structure mlx-vlm expects appear not to match.
The server starts even when loading fails
If the server cannot load the model, it switches to "random legal move mode" and opens the port anyway. The monitoring script only checks whether the port responds, so it judges the server healthy. Choosing the VLM on the screen returned a random legal move.
The log holds only more than 30,000 connects and disconnects, and there is no way to tell which connections were actual game requests. That is why we cannot know how many of the 31 games in post 1 were against the VLM.
Paths to random moves
Even after the model has loaded, there are three paths that switch to a random move.
- When an error occurs during inference
- When the model passes even though there is a place to play
- When the model picks an unplayable square or a forbidden coordinate
The web screen switches back to the local AI if the VLM's answer is an unplayable square. The local AI currently deployed is the one-move AI from post 2. Either way, the screen shows it as the VLM's move. In Go we decided never to secretly substitute an arbitrary move, but Othello was built the opposite way.
The actual code for this step
This is the part that clears model and keeps the server running when loading fails.
vlm_server/server.py
model: Optional[_MlxVlmModel] = None
if load_model:
    model = _MlxVlmModel(model_id, max_new_tokens=max_new_tokens, temperature=temperature)
    try:
        model.start(wait_load=True)
    except BaseException as e:
        LOGGER.exception("모델 로드 실패 → 무작위 합법수 모드: %s", e)
        model = None
This is the part that receives a request and decides the move. If there is no model or the answer is not a legal move, it picks at random.
vlm_server/server.py
model = self.server.model
row = col = None
is_pass = False
if model is not None:
    try:
        row, col, is_pass = model.predict_move(
            img, board, ai_side, legal, forbidden=list(bans), timeout_s=180.0
        )
    except Exception as e:
        LOGGER.warning("VLM 추론 실패, 합법수 무작위: %s", e)
        row = col = None
        is_pass = False

if is_pass:
    LOGGER.info("모델 PASS (합법수 있음) → 합법수 무작위")
    row = col = None

if row is None or col is None or (row, col) not in legal or (row, col) in bans:
    if row is not None and col is not None:
        LOGGER.info("불법/금지 (%s,%s) → 합법수 무작위", row, col)
    pick = _choose_legal(legal, bans)
    if pick is None:
        _send_pass(sock)
        continue
    row, col = pick

# ...

def _choose_legal(
    legal: list[tuple[int, int]], forbidden: set[tuple[int, int]]
) -> Optional[tuple[int, int]]:
    remain = [m for m in legal if m not in forbidden]
    pool = remain or legal
    if not pool:
        return None
    return random.choice(pool)
The next post is "4. A plan to bring what we learned from Go and Gomoku to Othello".
COMMENTS · CHAPTER 03
The VLM never played a move: Gemma 4 failed to load 0 comments
No comments yet. Leave a question or anything you would like to add.
To post a comment, continue with Google and register a nickname and email address.
Continue with Google