What the VLM is learning now
Automatic training collects only the winning side's moves and has the VLM imitate them. But in the training games White (the VLM) won 94%, and White's moves were recorded as if the local AI had played them. So 10,513 of the 12,080 examples were White's moves, that is, moves the VLM itself had played. As we saw in post 1, even that training broke with a NaN loss.
The question sent to the VLM contains no Gomoku rules either. It shows the board and asks only for two numbers, the coordinates of an empty cell. Words like three, four or forbidden move never appear.
What we learned from Go and the tile puzzle
In Go, while fixing the heuristic and playing it against R5, the heuristic ended up teaching R5. In the tile puzzle, putting the rules people use into the heuristic let it solve all 4,000 boards in one day. Both times, rules without greed opened the way before training that chases future reward.
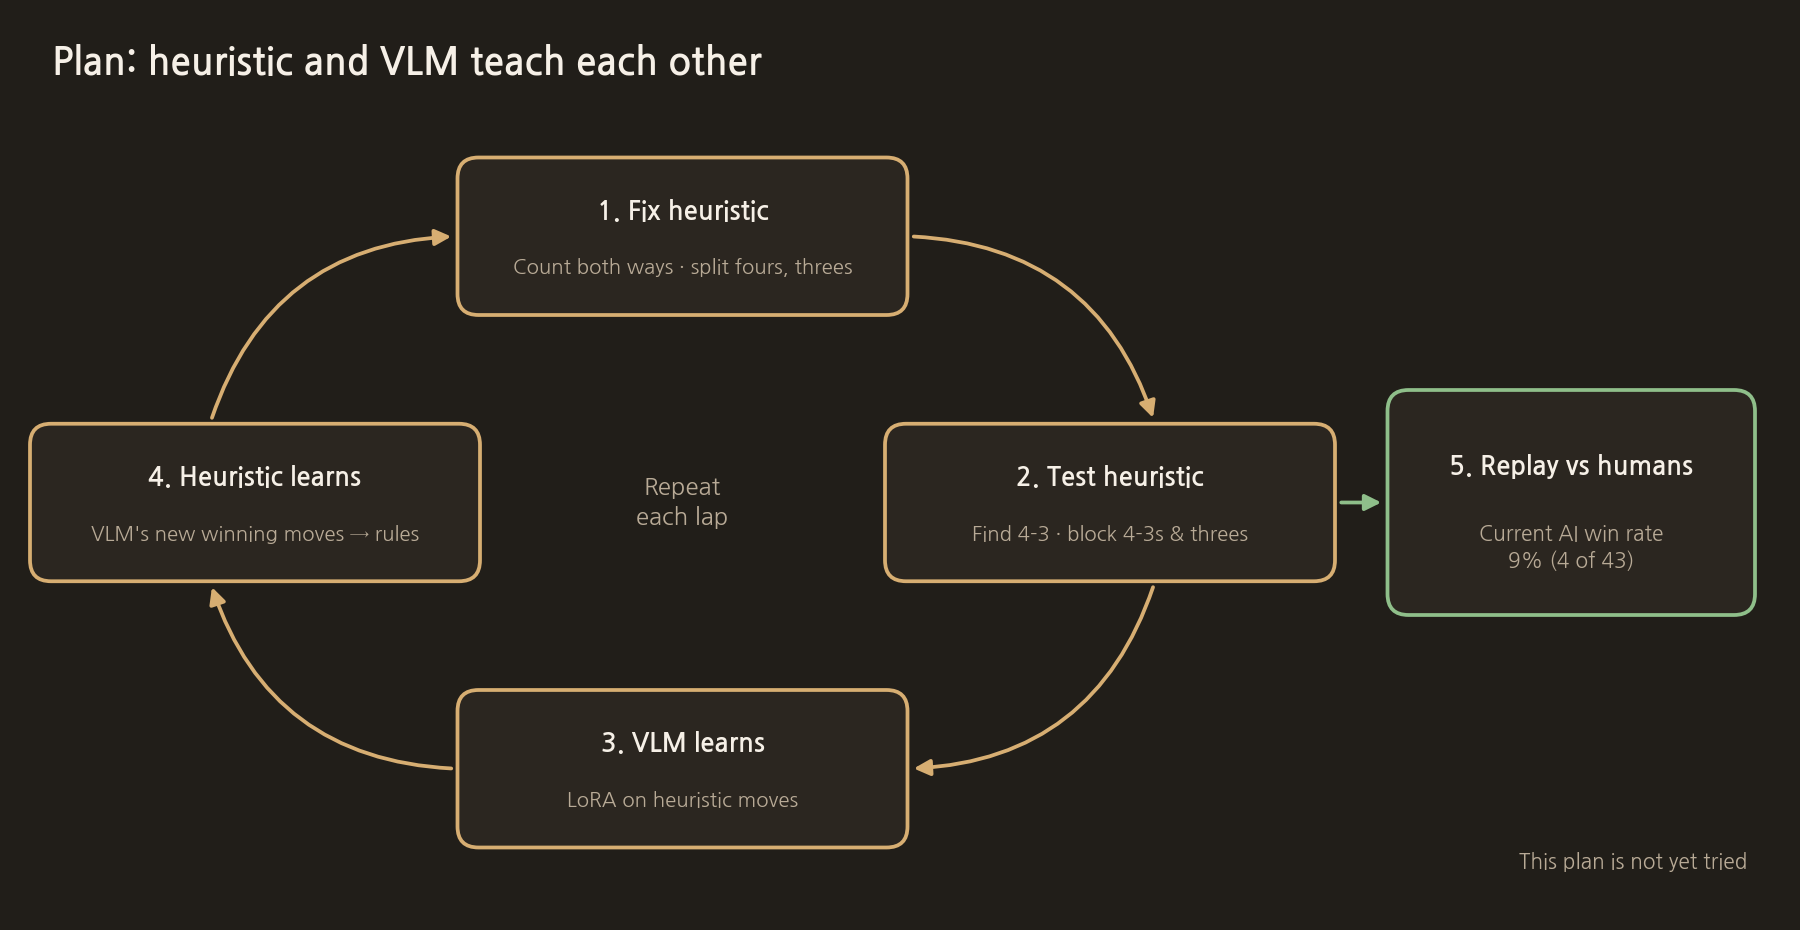
We plan to try the same approach for Gomoku. This plan has not been tried yet.
The plan
- Fix the heuristic: count each line in both directions, and count broken fours (○_○○○) and broken threes as the same shapes. Find its own four-three spots first, and block in advance the spots where the opponent could make a four-three or an open four on the next move.
- Test the heuristic: rerun the tests from post 3 (finding its own four-three, blocking the opponent's four-three spot, blocking threes) every time, and recheck whether the rules favour one side with games where the same AI alternates between Black and White.
- Have the VLM learn the heuristic: retrain LoRA with the fixed heuristic's moves as the answers. Add forbidden moves and threat shapes to the question, and first fix the broken training setting (MPS fp16).
- Make the heuristic the teacher again: collect moves where the VLM played differently from the heuristic and won, and move those shapes back into the heuristic's rules. This is how R5 and the heuristic learned from each other in Go.
- Play people again: judge by how much the AI's win rate against people rises from the current 9% (4 of 43 games).
The actual code for this step
This is the question currently sent to the VLM. It asks only for empty-cell coordinates and contains no Gomoku rules.
vlm_pva_server.py
base_prompt = (
    f"{turn_line}\n"
    f"{board_txt}\n"
    f"Choose your next {you_label} move on an EMPTY cell (a '.' in the TEXT board)."
    f"{opening_rule} "
    "Trust the TEXT board coordinates over the image. "
    "Reply with EXACTLY two integers separated by a single space: \"row col\". "
    f"row and col are both in 0..{last_idx}. No other text."
)
The next post is "5. The full source code and the models used".
COMMENTS · CHAPTER 04
A plan for the VLM to learn the heuristic, and for the heuristic to become the teacher again 0 comments
No comments yet. Leave a question or anything you would like to add.
To post a comment, continue with Google and register a nickname and email address.
Continue with Google